LLM integration & model routing
The right model for each request, and a fallback when one fails.
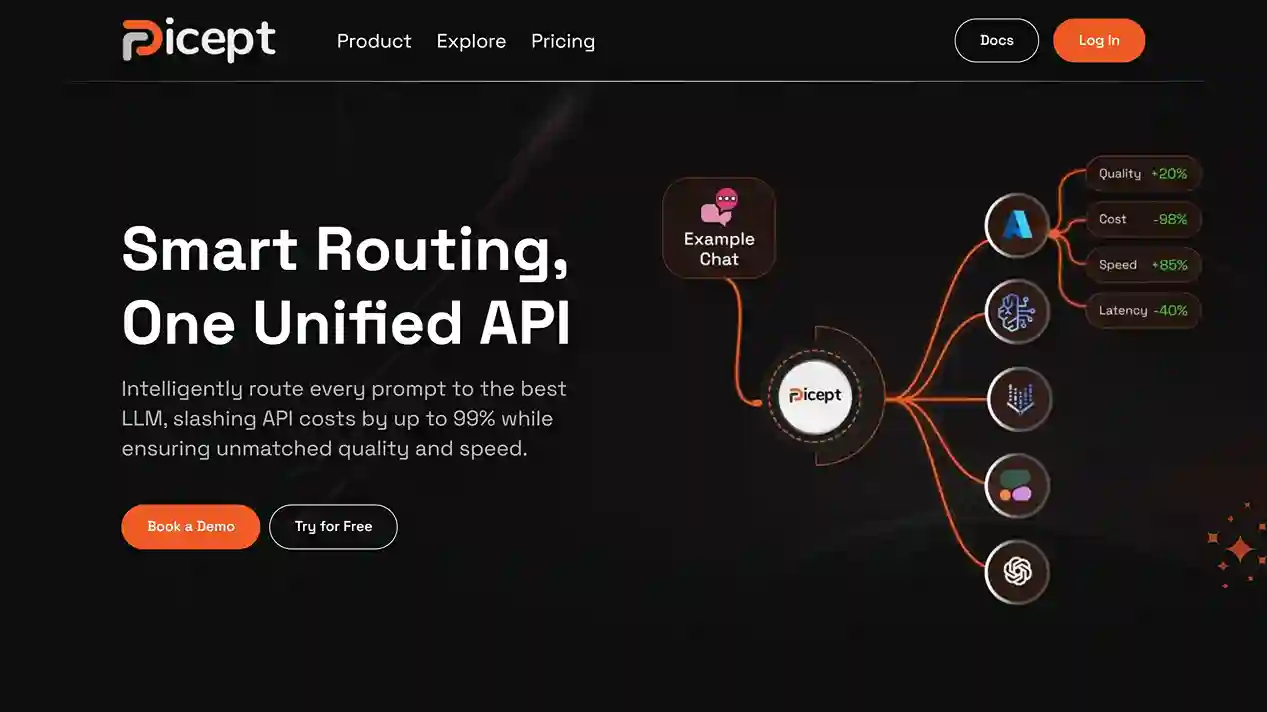
We add LLMs to the product you already run and route each request across providers by cost, speed and quality, with fallbacks, caching and the observability to see what every call costs.
Typical timeline: 2–5 weeks
Capabilities
What's included
- LLM features wired into your existing backend and UI
- Multi-provider routing across OpenAI, Anthropic, Google and open models
- Automatic fallbacks, retries and rate-limit handling
- Prompt management and versioning outside the codebase
- Response caching and token budgets to control spend
- Observability: latency, cost and quality per model and feature
- Evals to compare models before you switch
How we work
From brief to live
- 01
Audit
2–4 daysCurrent calls, costs and quality, and where a cheaper or faster model would do.
- 02
Integrate
1–3 weeksRouting layer, fallbacks and observability, rolled out behind a flag.
- 03
Optimise
2 weeksEvals and cost data used to tune routing rules after launch.
FAQ
Good to know
No. That is the point of routing: switching models becomes a configuration change, tested with evals first.
Usually. Many requests do not need the largest model; routing them to smaller ones and caching repeats cuts spend without hurting quality on your evals.
Have something in mind?
Send a short brief or book a 20-minute call. We reply within one working day.